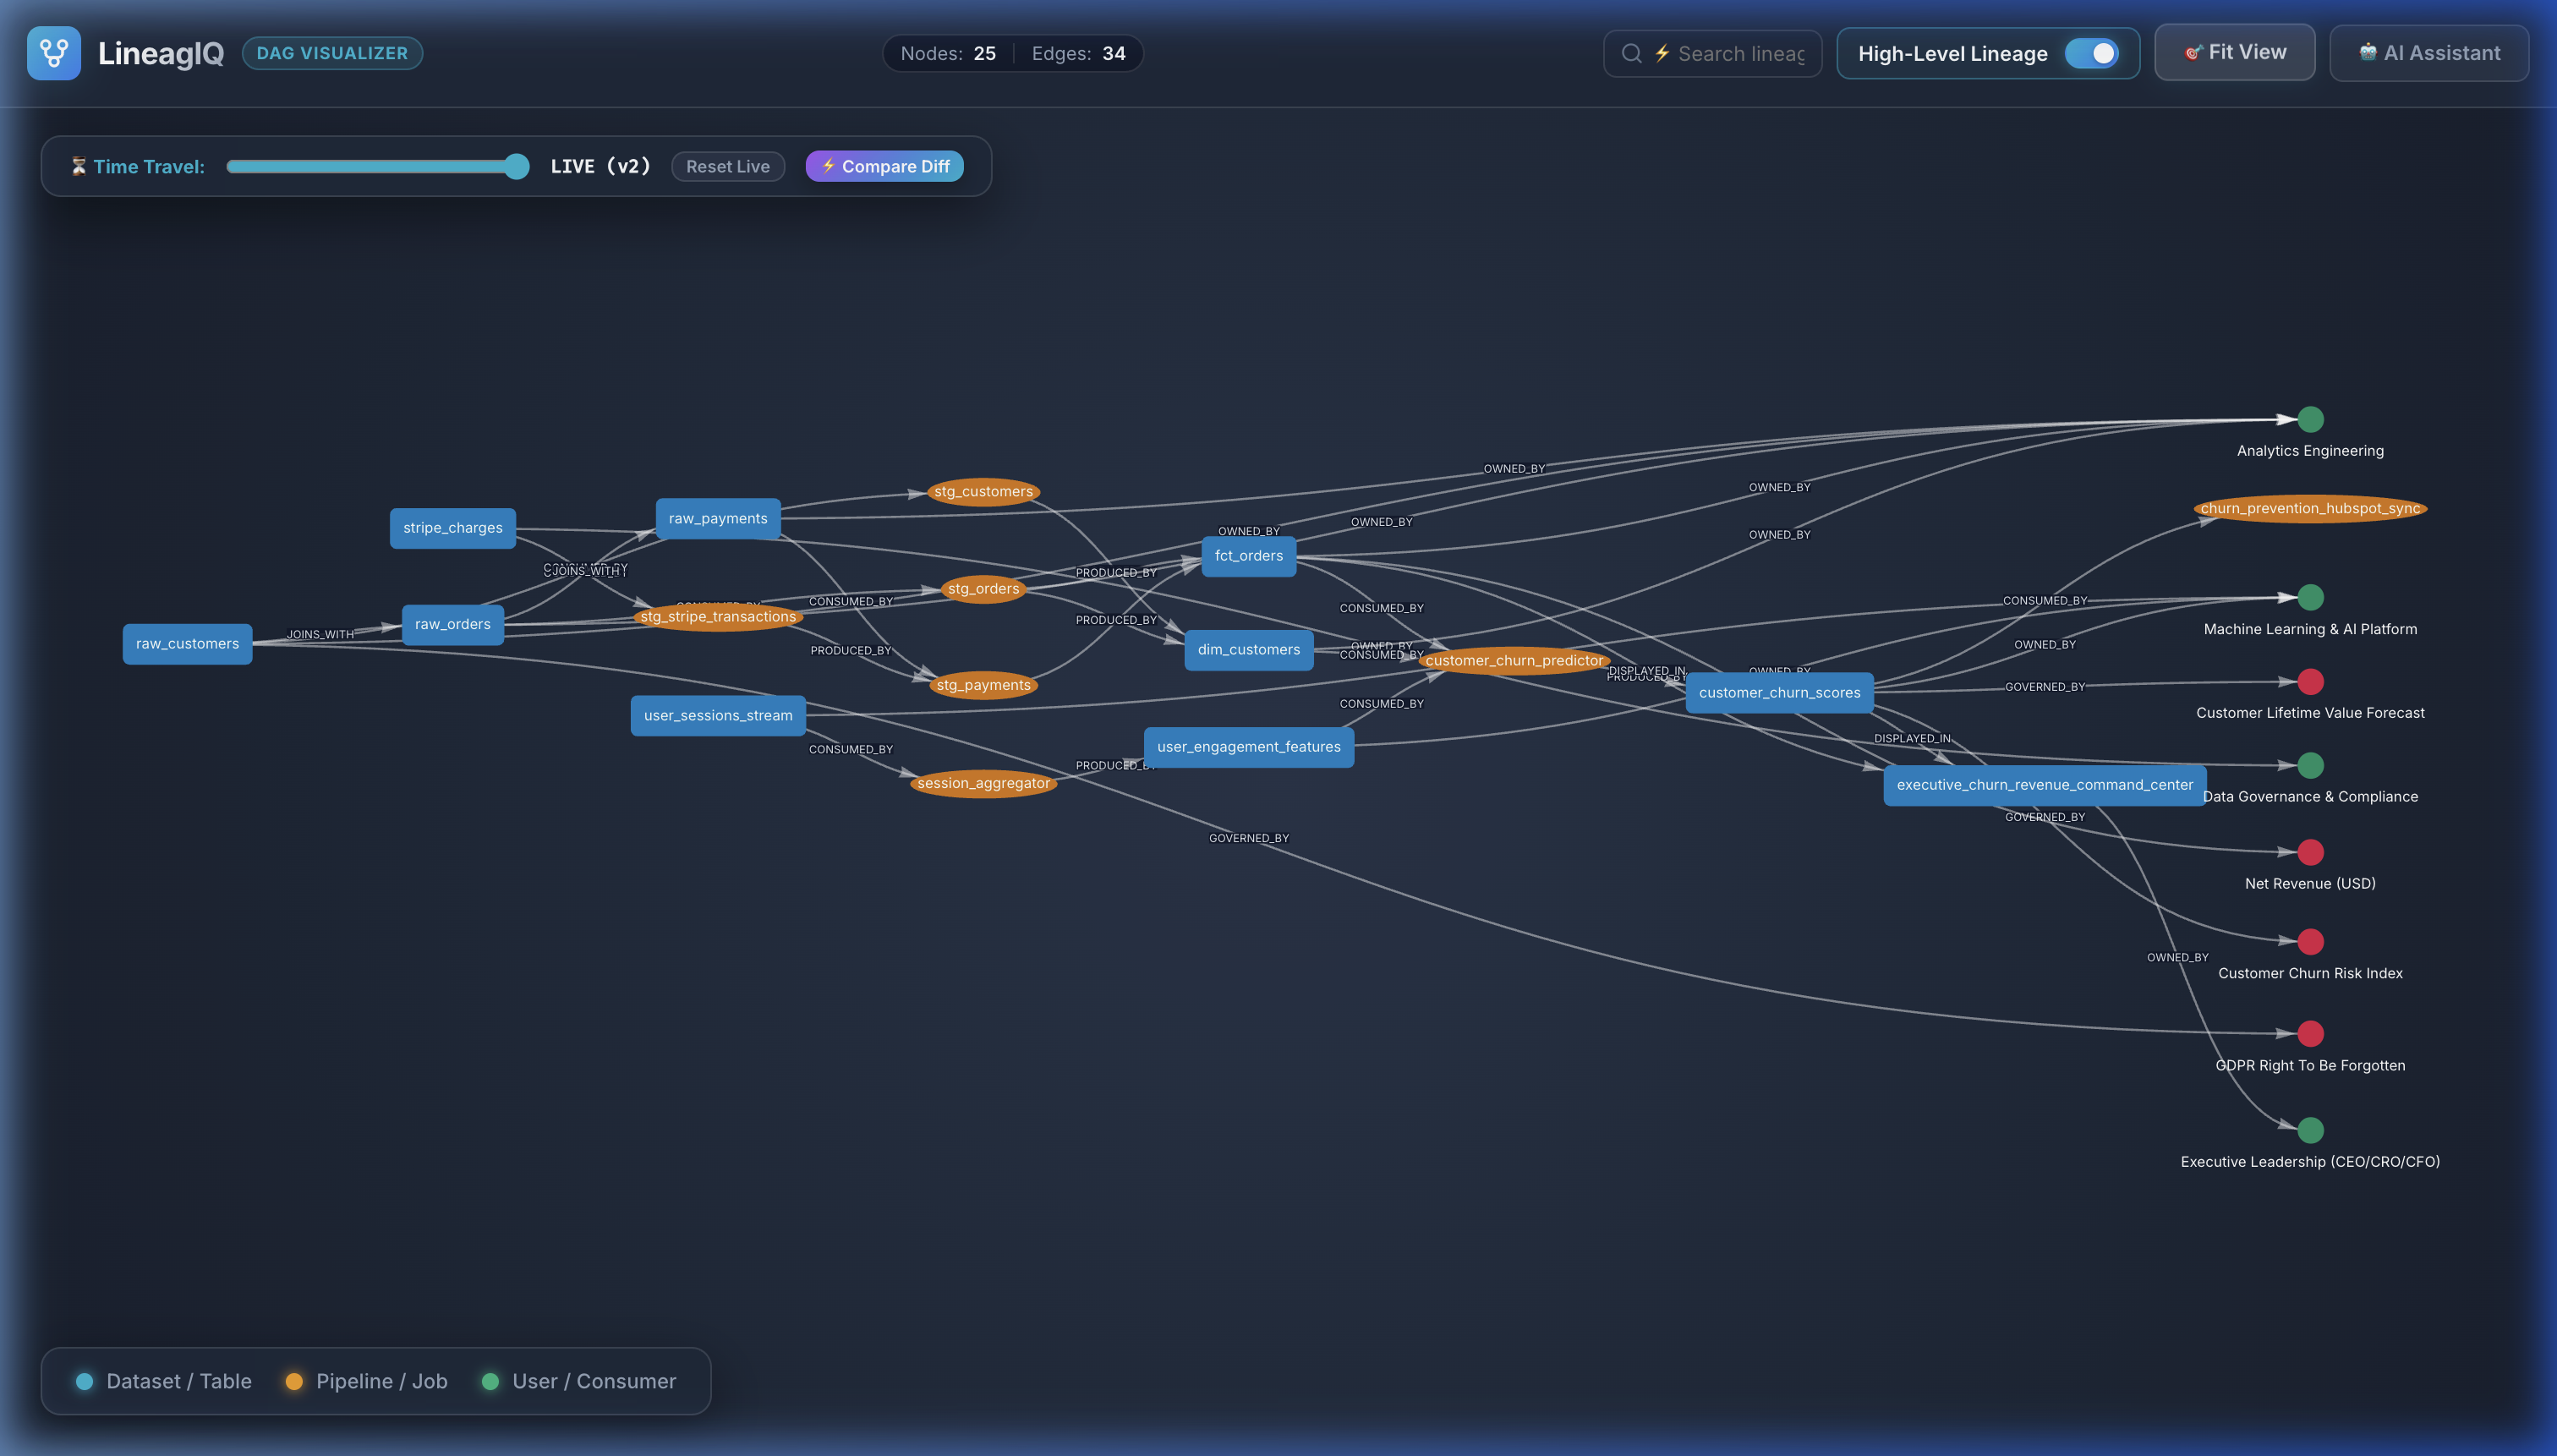
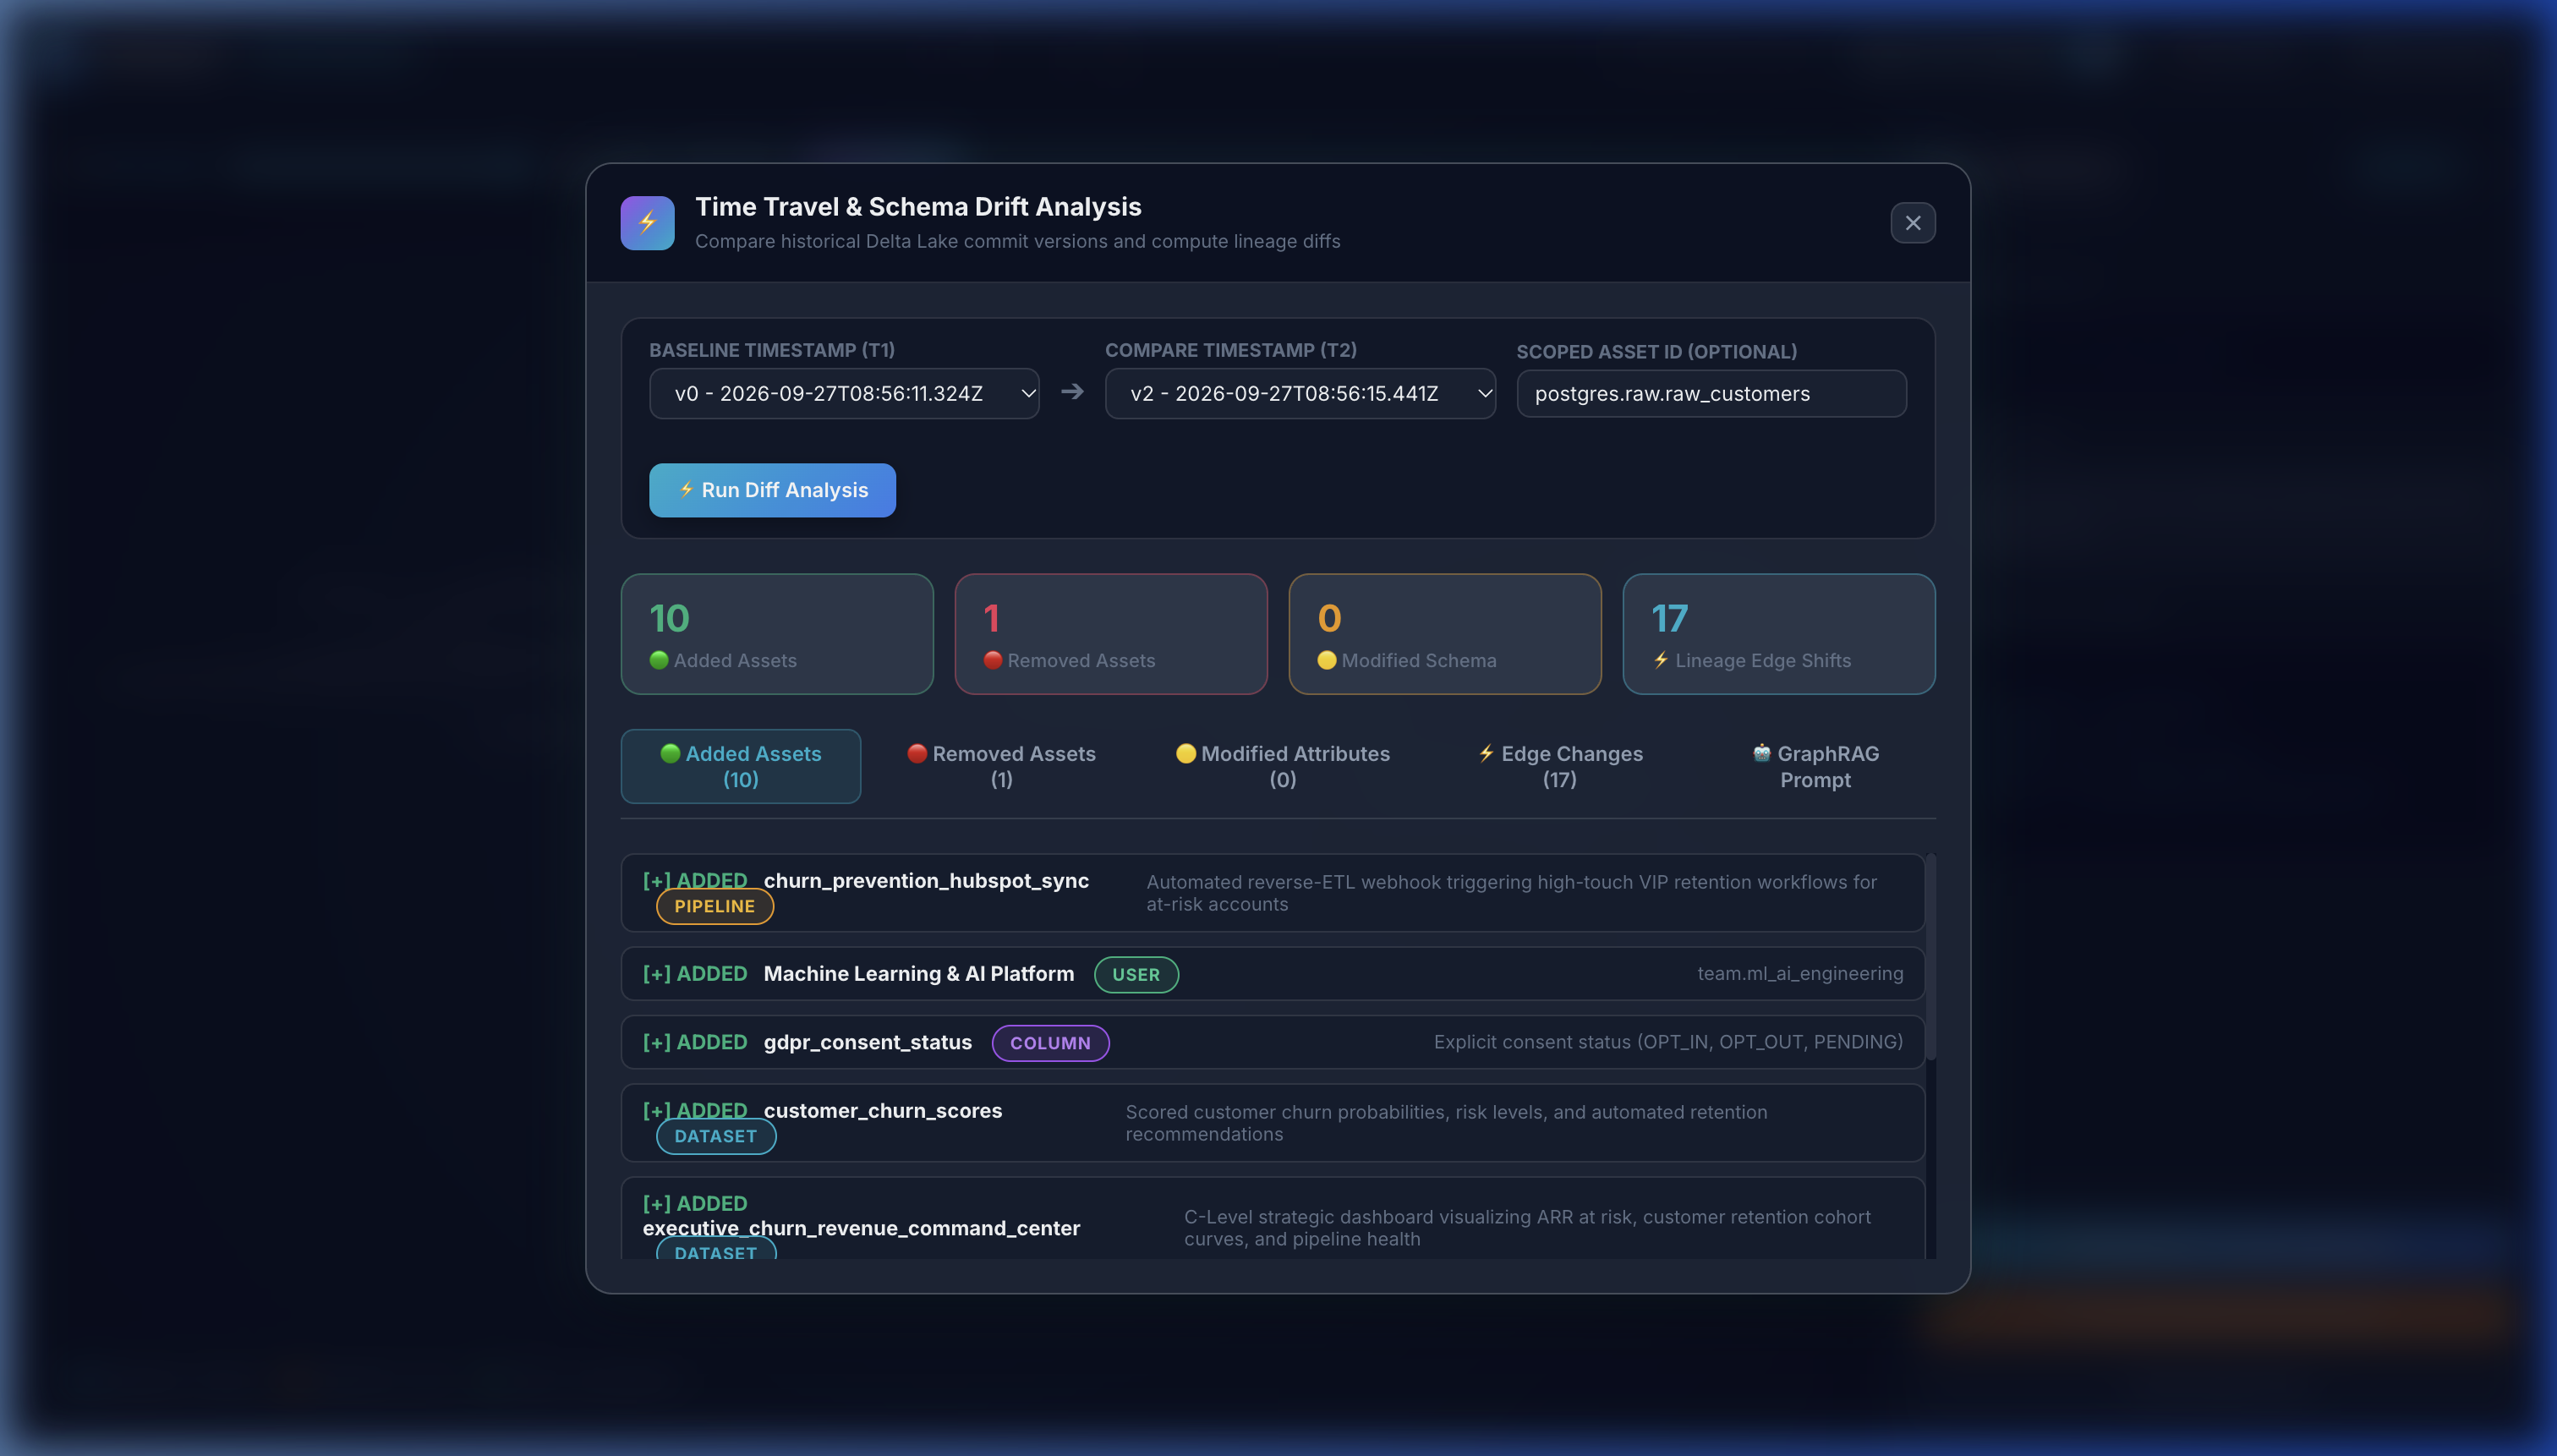
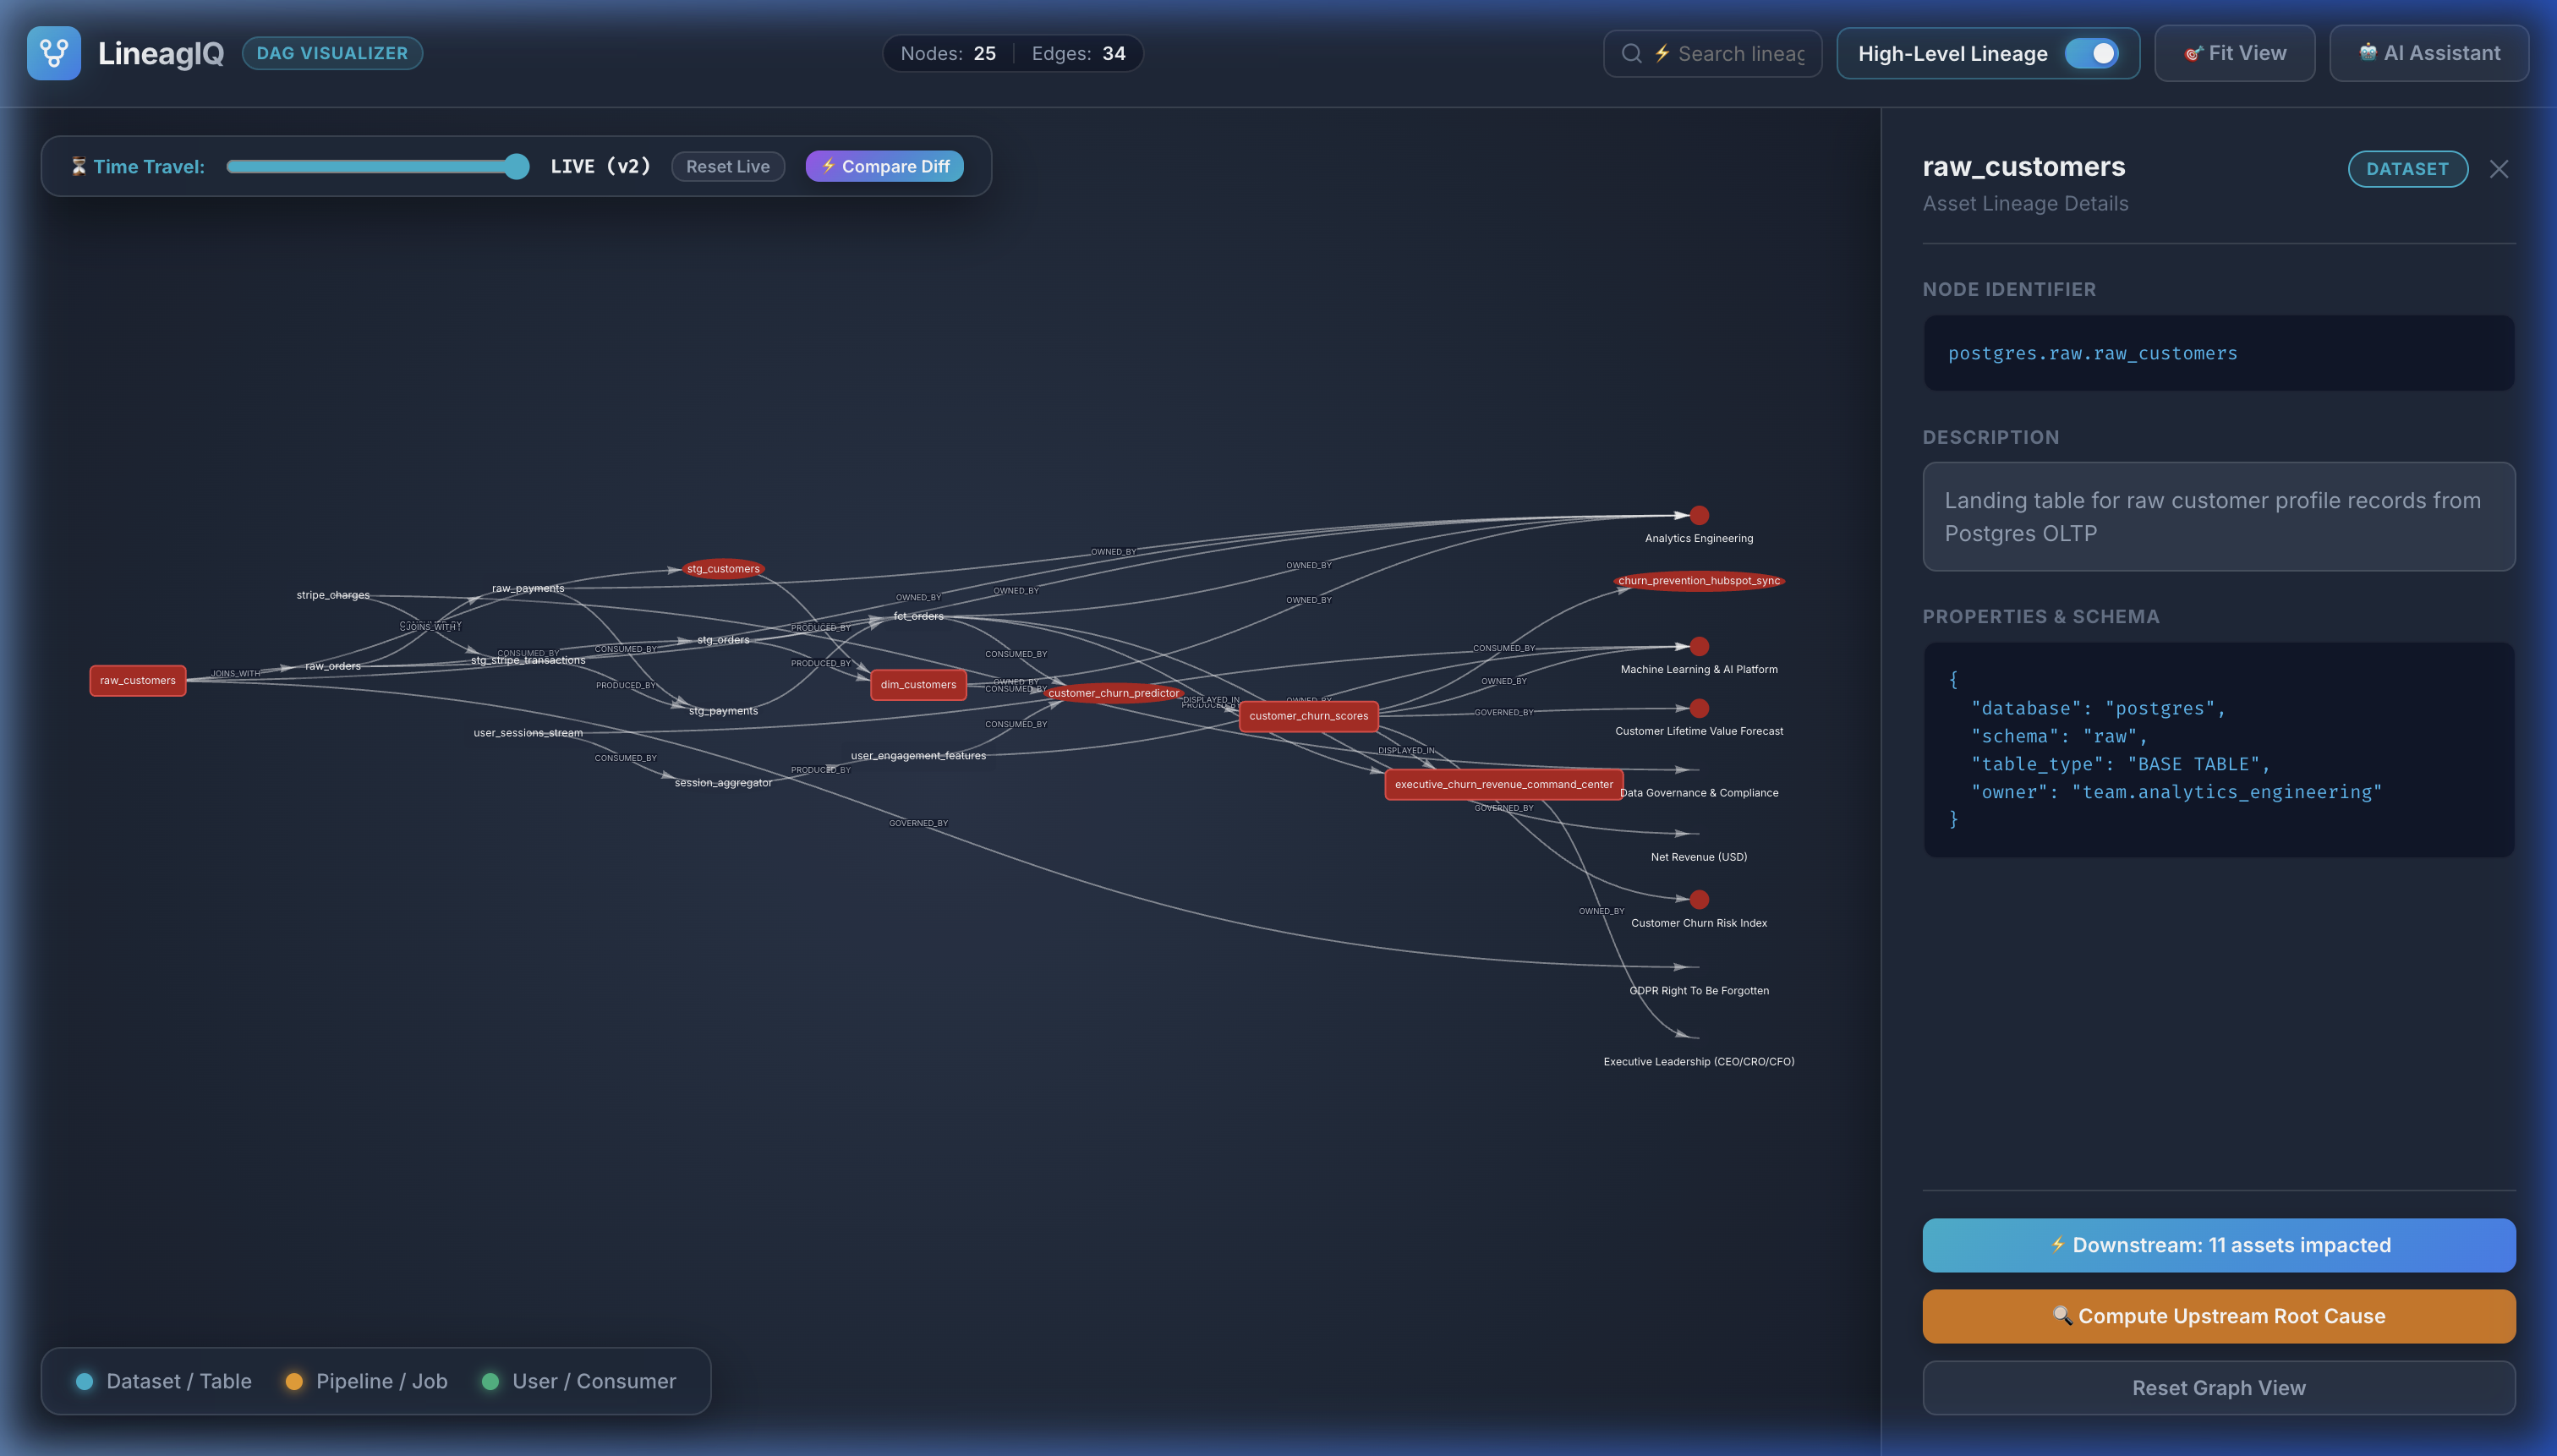
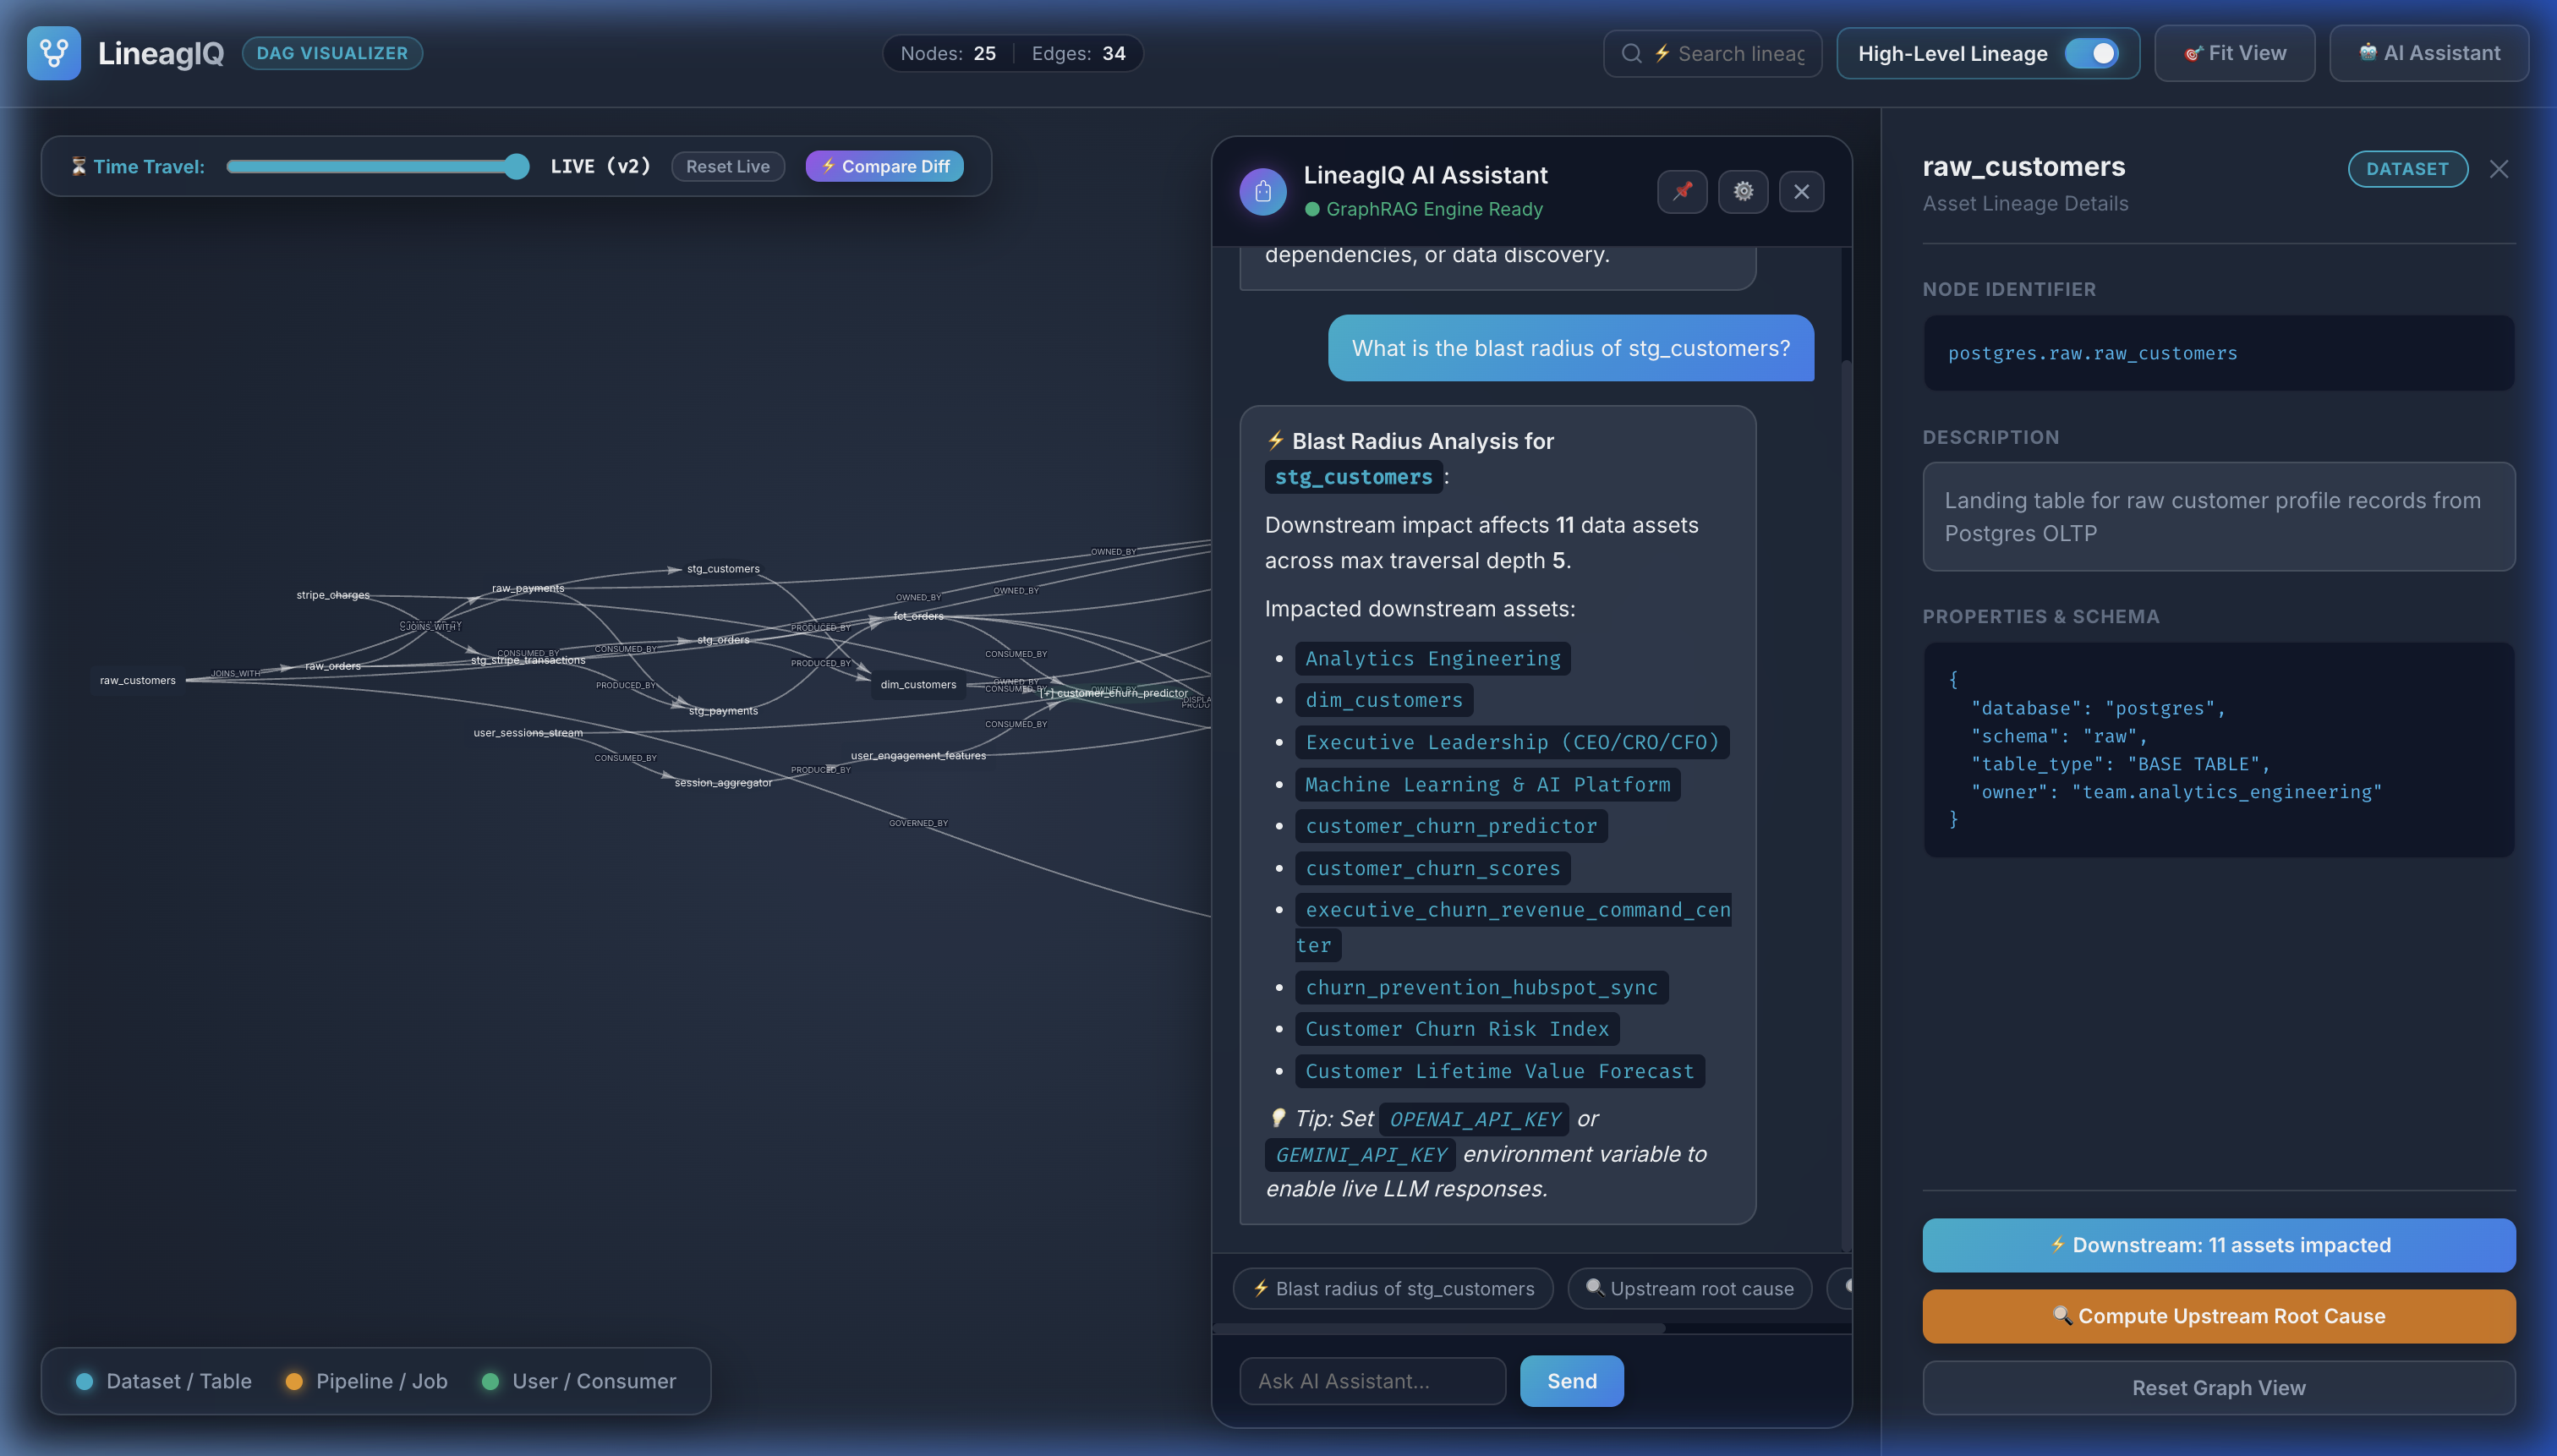
LineagIQ unifies fragmented, multi-cloud data pipelines into an active, queryable semantic knowledge graph. Experience point-in-time schema drift analysis, instant recursive blast-radius attribution, and an ultra-lean serverless architecture that completely eliminates expensive, dedicated graph database clusters.
Data pipelines fail silently when upstream tables alter column types, rename keys, or drop fields unannounced. LineagIQ captures every structural revision and dependency shift across time through Delta Lake's ACID transactional commit logs.
Before deploying schema migrations or refactoring dbt models, LineagIQ computes downstream blast radius in milliseconds—preventing downstream data incidents and broken executive dashboards.
LineagIQ bridges graph intelligence with generative AI through Graph-Augmented Generation (GraphRAG). Ground your LLMs with deep structural lineage context to eliminate hallucinations during architectural audits and incident investigations.
The LineagIQ Collection Agent operates as a lightweight, stateless utility inside your secure VPC, CI/CD pipeline, or Kubernetes cluster. It ingests schema definitions, warehouse catalogs, audit logs, and runtime orchestrator events—transforming raw operational signals into unified graph models and semantic vector embeddings without ever touching raw customer record data.
Directly ingests compilation artifacts (manifest.json and catalog.json). Extracts data models, seeds, snapshots, source declarations, column-level documentation, tags, and tests, compiling the complete transformation DAG into unified DERIVED_FROM dependency edges.
python -m collection_agent.src.cli --dbt-manifest <path> --dbt-catalog <path>
Parses standard INFORMATION_SCHEMA.TABLES, COLUMNS, and foreign key constraint definitions. Extracts relational schemas, column data types, ordinal positions, and physical JOINS_WITH relationships across relational databases and cloud warehouses.
python -m collection_agent.src.cli --sql-schema <path_to_schema.json>
Analyzes warehouse audit histories (Snowflake QUERY_HISTORY, BigQuery INFORMATION_SCHEMA.JOBS, Databricks Query History). Mines actual user and service dataset consumption patterns (CONSUMED_BY), query execution frequencies, and implicit multi-table join predicates.
python -m collection_agent.src.cli --query-logs <path_to_logs.json>
Ingests standardized OpenLineage JSON run events emitted by workflow orchestrators and distributed compute engines. Seamlessly maps job run IDs, execution timestamps, input dataset consumption edges (CONSUMED_BY), and output production edges (PRODUCED_BY).
python -m collection_agent.src.cli --openlineage <path_to_events.json>
Legacy enterprise data catalogs mandate dedicated Neo4j, TigerGraph, or Amazon Neptune clusters—burdening teams with persistent infrastructure bills, JVM memory management, and specialized graph query skills. LineagIQ re-architects graph intelligence from first principles.
Thanks to LineagIQ's versioned snapshot materialization, historical graph partitions are dynamically cached in LineagIQ's in-memory columnar engine. Bit-packed, dictionary-encoded relations achieve sub-10ms recursive CTE query execution on ultra-compact hardware—eliminating expensive multi-node graph database clusters entirely.
| Scale Tier | Graph Topology (Nodes & Edges) | In-Memory Cache Footprint | Recommended Hardware | Recursive Traversal Latency | Legacy JVM Graph Equivalent |
|---|---|---|---|---|---|
| Mid-Market | 50,000 nodes • 150,000 edges | ~25 MB – 45 MB |
0.5 vCPU, 1 GB RAM (e.g., ~$10–$20/mo) | < 8 ms | 16 GB RAM Neo4j (~$300/mo) |
| Enterprise | 250,000 nodes • 1,200,000 edges | ~180 MB – 320 MB |
1 vCPU, 2 GB RAM (e.g., ~$30/mo) | < 18 ms | 32 GB RAM Neptune (~$850/mo) |
| Large Enterprise | 1,000,000 nodes • 5,000,000 edges | ~650 MB – 1.1 GB |
2 vCPU, 4 GB RAM (e.g., ~$50/mo) | < 45 ms | 64 GB RAM HA Cluster (~$2,200/mo) |
| Hyperscale Global | 5,000,000+ nodes • 25,000,000+ edges | ~3.2 GB – 5.8 GB |
4 vCPU, 8–16 GB RAM (e.g., ~$90/mo) | < 95 ms | 128 GB+ Distributed Cluster ($5,000+/mo) |
Designed for platform architects, data engineers, and AI developers. LineagIQ cleanly decouples edge metadata extraction, immutable table storage, and vectorized query execution.
Executes as an ephemeral batch task (Docker, Kubernetes CronJob, or GitHub Action) inside customer boundaries. Ingests metadata from files, schemas, query logs, and orchestrators.
Standard cloud object storage (S3/GCS) or enterprise storage layer. Stores lineage nodes, dependency edges, schema definitions, and vector embeddings backed by Delta Lake transaction logs.
FastAPI query runtime running an embedded vectorized engine to execute multi-hop lineage traversals directly against Delta tables. Exposes sub-second REST endpoints, interactive graph visualizations, and GraphRAG tools.
Embed LineagIQ's lineage intelligence and blast-radius tools into agentic Python workflows (LangChain, AutoGen, LlamaIndex, or CrewAI) with minimal boilerplate:
from openai import OpenAI
from control_plane.src.agent_tools import (
get_dataset_blast_radius,
get_lineage_time_travel_diff
)
# 1. Retrieve Graph Context & Synthesized GraphRAG Prompt
blast_radius_prompt = get_dataset_blast_radius(
node_id="postgres.raw.raw_customers",
max_depth=5
)
# 2. Dispatch Context to LLM of your choice (OpenAI, Gemini, or local Ollama)
client = OpenAI()
response = client.chat.completions.create(
model="gpt-4o",
messages=[
{"role": "system", "content": "You are LineagIQ AI Agent, an expert enterprise data architect."},
{"role": "user", "content": blast_radius_prompt}
]
)
print(response.choices[0].message.content)
Pull pre-built, production-ready multi-architecture containers directly from GitHub Container Registry. No local Python build or cloud setup required.
ghcr.io/timor-dataworks/lineagiq-control-plane:latest
ghcr.io/timor-dataworks/lineagiq-collection-agent:latest
Run the ephemeral agent to generate a 3-version historical lineage evolution dataset (or point to your own dbt manifests / SQL catalogs).
docker run --rm \
-v $(pwd)/data:/data \
ghcr.io/timor-dataworks/lineagiq-collection-agent:latest \
--multiversion-demo
./data (Delta Lake tables: nodes, edges, vectors, commit logs).
Start the query runtime. LineagIQ mounts your Delta Lake directory and immediately serves the interactive visualizer and REST APIs.
docker run -d --name lineagiq-control-plane \
-p 8000:8000 \
-e DATA_PATH=/data \
-v $(pwd)/data:/data \
ghcr.io/timor-dataworks/lineagiq-control-plane:latest
http://localhost:8000 with sub-second response times.
Spin up the complete pipeline (demo dataset generation + serverless control plane) with a single command:
# Download docker-compose.yml and start stack
curl -sSL https://raw.githubusercontent.com/timor-dataworks/LineagIQ/main/docker-compose.yml -o docker-compose.yml
docker compose run --rm demo_generator
docker compose up -d control_plane